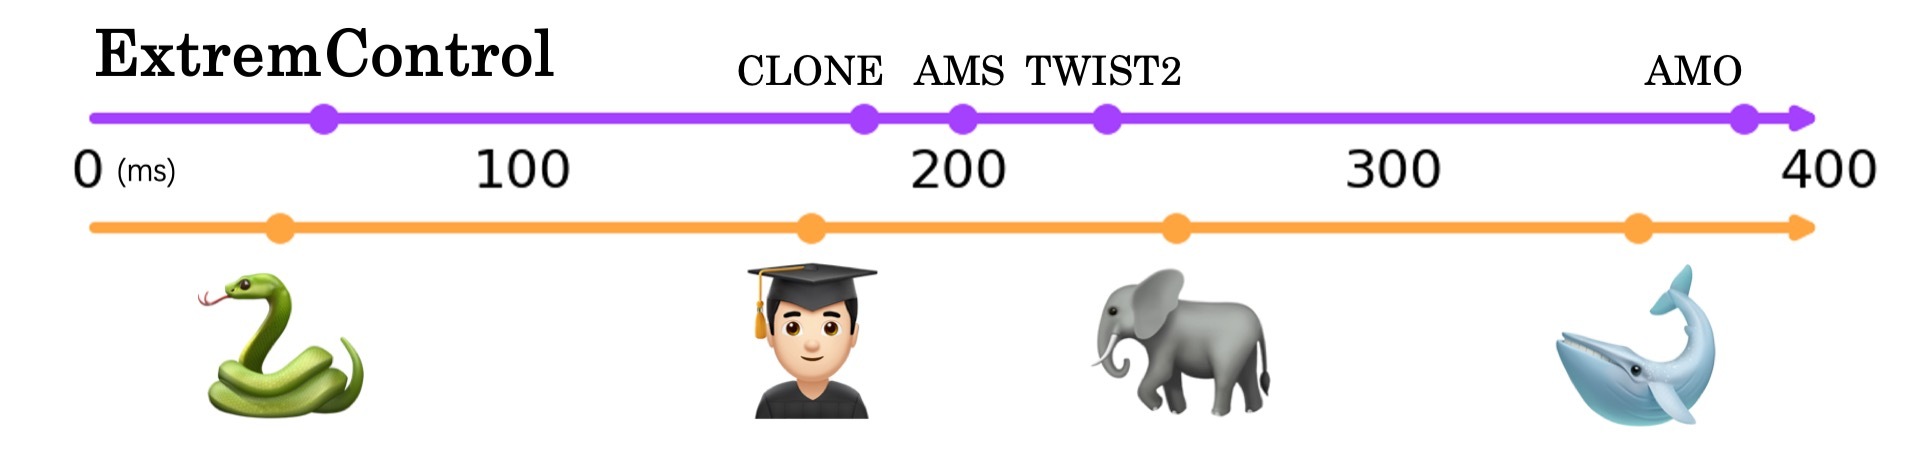
Since the very beginning of parallel simulation for locomotion, position-only PD control seems to be the only option. However, due to the damping term, the target joint position must lead the actual position by a certain angle to maintain the joint velocity, deviating from the definition of "target" joint position. To address this issue, we introduce a velocity feedforward term where the target velocity is computed from the difference betweenlast two target joint positions. To prevent overshoot, the velocity gain is set as the damping gain scaled by a feedforward ratio smaller than 1. We derive a theoretical upper bound in our paper, which is further validated through experiments.
We also provide a demonstration of how velocity feedforward term affects the control behavior: